
Most "AI content engines" are duct tape. You prompt ChatGPT, paste the draft into Docs, run it through Grammarly, paste into Surfer for keyword polish, log into WordPress, fix the formatting, click publish, then refresh Search Console for a week hoping it indexed. Each handoff drops context. By the third post, the workflow has already broken.
Quick answer: A Claude Code content engine is a recurring publishing system that uses Claude Code (Anthropic's CLI agent) plus Model Context Protocol servers to research, draft, SEO-score, publish, and refresh blog content end-to-end from one terminal session. It removes the copy-paste loop between your AI and your CMS.
This guide covers the 6-stage loop, the minimum MCP stack, a copyable CLAUDE.md, and the one component nobody builds until it's too late — a publishing throttle. We know that last one because we ran our own engine without it and put a third of our library out of Google's index.
What a Claude Code content engine actually is#
It's three things stacked: a CLI agent, a protocol, and a publishing target.
Claude Code is Anthropic's terminal-native agent. It reads your files, runs commands, edits drafts, and asks permission before anything destructive. It owns the shell rather than sitting in a chat box.
Model Context Protocol (MCP) is the open standard Anthropic released in November 2024 to connect agents to external systems — a USB-C port for AI. It's now governed by the Linux Foundation's Agentic AI Foundation, with OpenAI, Google, Microsoft, AWS, and Cloudflare all shipping support.
The publishing target is whatever serves your blog at yourdomain.com/blog. This part is not negotiable. Posts that live on someplatform.com/yourname build authority for the platform's root domain, not yours. Two years in you'd have 240 posts and nothing to show for your own domain.
Why the copy-paste stack collapses in 2026#
The traditional workflow assumes a stable SERP and patient readers. Neither exists now.
Position-one CTR drops 58% when an AI Overview appears above the blue links. Brands cited inside an AI Overview earn roughly 120% more organic clicks per impression than uncited brands on the same query — so not being cited isn't "less traffic," it's no traffic.
Freshness got brutal too. An AirOps study of 548,534 pages across 15,000 prompts found ChatGPT cites only 15% of pages it retrieves. Of those it does cite, 76.4% were updated in the last thirty days and 50% are under thirteen weeks old. Pages past the one-year mark drop out of citation pools almost entirely.
A workflow that takes four to nine hours per post cannot service a freshness window measured in weeks. That math is what forces consolidation.
The 6-Stage Content Loop#
Every working content engine follows the same loop. The labels change; the order doesn't.
Stage | Goal | What the agent does | MCP server type |
|---|---|---|---|
1. Research | Find a winnable topic | SERP scrape, PAA harvest, GSC query mining | Search, GSC, scraper |
2. Draft | Produce a publish-ready post | Long-form generation with project context | Filesystem, knowledge base |
3. Score | Pass an SEO + AEO bar | Pull patches, apply fixes | SEO scoring |
4. Publish | Ship to your own domain | Publish, regenerate sitemap | Publishing, CMS |
5. Monitor | Detect index + citation | Watch GSC and AI surfaces | GSC, AI tracking |
6. Refresh | Update before decay | Patch stats, headings, intro | SEO scoring, publishing |
Call it the 6-Stage Content Loop. The names matter because most "AI blog tool" pitches collapse stages 2–4 into "generation" and quietly skip 5 and 6. Skip monitoring and you can't tell whether you ranked. Skip refresh and everything you ship has a 90-day half-life.
Two stages deserve specific attention.
Stage 1 has one non-obvious rule: mine Search Console before you pick the keyword. Posts targeting queries you already rank 11–30 for break the first page far more often than cold-start keywords. Your engine has to know which keywords are already warm. Our 5-layer ranking fix stack covers why most research stages produce thin briefs.
Stage 3 is where drafts become posts. The loop is mechanical: create_content saves and scores, get_blog_seo_patches returns find-and-replace fixes with a point impact each, update_content applies them in one call, repeat until the score clears 85. You never eyeball "is this SEO good" — the tool says "+8 for a shorter meta description, +6 for two more internal links." For what each category checks, see how the SEO score is calculated.
The failure mode at stage 3 is "publish and hope." Posts that ship at 60 because the operator ran out of patience never recover.
Stage 6 is the one everyone skips#
Freshness is the dirtiest secret of AI search. People assume rankings are stable. They aren't.
A working engine refreshes on three tiers:
30 days for anything chasing a "this year" keyword — update the year, the freshest stat, the intro.
90 days for evergreen-leaning posts — refresh stats, swap an outdated source, re-score.
180 days for true evergreens — full re-read and re-score.
The contrarian point: refresh beats new posts. A post that already indexed and earned backlinks is a higher-leverage asset than a cold-start draft. Most operators write because writing feels productive. The engine refreshes because refreshing is what compounds.
The minimum MCP stack#
You don't need fifty servers. You need six.
Layer | What it does | Recommended | Notes |
|---|---|---|---|
Search | SERP, news, PAA | Exa or Tavily | Exa has cleaner output |
Fetch | URL → markdown | Firecrawl or Fetch | Firecrawl handles JS-rendered pages |
Knowledge | Filesystem + notes | Built-in Filesystem | Ships with Claude Code |
Search Console | Query mining, indexing | GSC MCP or Quillly | Quillly bundles it with publishing |
SEO scoring | Scoring + patches | Quillly | Returns ready-to-apply patches |
Publishing | Push to your own domain | Quillly |
|
Every MCP server is a token tax — each one's tool descriptions load into context every session. Combining scoring, GSC, and publishing into one server costs less context than three separate ones. For the wider landscape, see our builder's guide to MCP servers for SEO.
Cost: Claude Code is included with the Anthropic plan you already pay for. Most MCP servers are free or open source. Quillly is $9/month or $96/year after a 14-day trial that needs no card — five sites, unlimited content, the full MCP tool set. Wire it up in under a minute.
A copyable CLAUDE.md for content engines#
Drop this at the root of your content project. Rename the placeholders and tighten as your voice sharpens.
# Content Engine — CLAUDE.md

## Role
You are the lead content writer for [BRAND]. You ship 2,000–2,800 word
blog posts engineered to rank in Google, be cited in AI Overviews,
and earn backlinks.

## Audience
[ONE-SENTENCE ICP: e.g. "Solo founders and indie hackers building
SaaS with AI tools."]

## Every post must
1. Answer one specific question the audience is searching.
2. Position [BRAND] as the solution in 2 places maximum.
3. Earn an AI citation by leading every section with the answer.

## Voice rules
- Grade 8–9 reading level. Short sentences.
- Contractions on ("don't", "you're").
- No "leverage", "utilize", "in today's fast-paced world",
  "in conclusion".
- Active voice. "You" addresses the reader.
- Definite language ("X means") over vague hedging.

## Structure rules
- No H1 in body. Title is rendered separately.
- Direct-answer block (40–60 words) within the first 200 words.
- 7–10 H2s. 120–180 words between headings.
- At least 5 statistics with source URLs.
- At least one comparison table (3+ rows).
- FAQ section with 5–7 Q/As, 40–60 words each.

## Internal link inventory
- /blog/[slug-1] — [one-line summary]
- /blog/[slug-2] — [one-line summary]
- (add every published post here)

## Forbidden
- Customer names without written permission.
- Statistics without source URLs.
- Claims you cannot back with a link.
Two things make this work. The structure rules are tight enough that the agent stops asking "should I do X?" and just does it. And the internal link inventory is the most under-used SEO asset most operators own — when the agent has every published post in context, it links naturally and your topical clusters tighten on their own.
The throttle: what happened when we ran ours flat out#
A content engine's failure mode isn't that it writes badly. It's that it writes faster than your domain can absorb. We know because we ran ours at full speed and measured the result.
Over one 30-day stretch our engine published 29 posts to quillly.com — roughly one a day, every one scored above the publish threshold, every one with images, internal links, and schema. By the engine's own metrics, a total success.
Here's what happened to the domain underneath it:
Metric | Result |
|---|---|
Posts published in 30 days | 29 |
Total published posts | 125 |
Indexed by Google | 76 (64%) |
Stuck in "Discovered – not indexed" | 85 URLs |
Stuck in "Crawled – not indexed" | 23 URLs |
Domain Rating | 12 |
Thirty-six percent of the library is invisible. Not badly ranked — not in the index at all.

The mechanism is crawl budget. A DR 12 domain gets a small, finite crawl allocation. Publishing a 126th post doesn't buy a 126th chance to rank — it splits the same allocation one more way and lowers the odds for the 125 already waiting. Past a certain rate, output and indexing move in opposite directions. It's also, uncomfortably, the exact behavioural signature Google's scaled-content-abuse policy is written to detect: high volume, uniform structure, low authority.
So the most important component in a content engine isn't the writing prompt. It's the throttle — a gate that reads live indexing data and refuses to publish when coverage is falling.
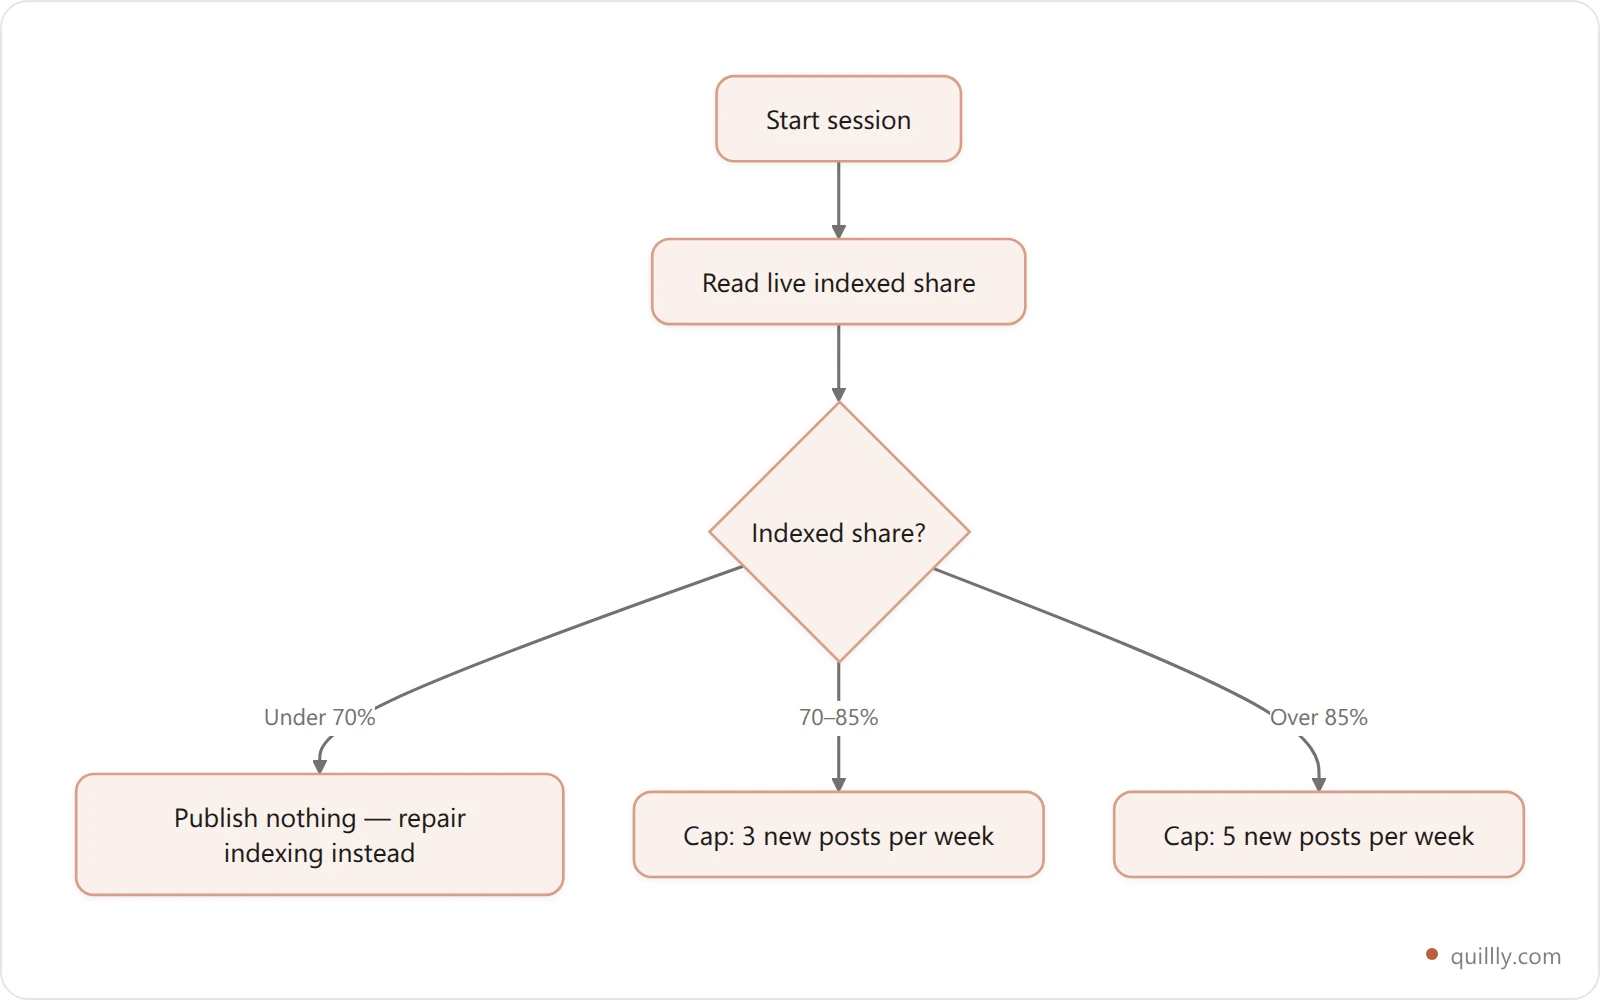
Before each run the agent reads the indexed share and computes the cap. When the gate is closed the engine still runs — it just spends the session strengthening existing posts and fixing indexing instead of adding to the queue. On the day of writing, our own cap was zero, and this section is what the engine produced instead of a new post.
Build the gate before you build the writer. An engine without a throttle isn't an engine, it's a firehose — and at DR 12 the domain is the thing that breaks. If your posts are stuck, our indexing fix stack covers the deeper causes.
Three mistakes that quietly kill content engines#
The failures aren't loud. The engine just stops compounding.
Treating "AI generates blogs" as the goal. Generation is the cheapest stage in the loop. The compounding stages are scoring, monitoring, and refreshing. Optimize for "how fast can I generate?" and you end up with a graveyard of 70-score drafts that never rank.
Running on a subdomain or shared platform. Every post shipped to someone else's domain is a deposit into their authority account. Our subdirectory vs subdomain breakdown shows the math.
Skipping the refresh queue. Invisible until month four. You ship eight posts, three index, traffic ticks up — then the freshness clock runs out and you blame the algorithm. The actual cause is eight posts written, zero refreshed. Rule of thumb: for every new post in week N, refresh one post from week N-12.
Frequently Asked Questions#
Do I have to know how to code to run a Claude Code content engine?#
No. You install Claude Code, run claude in a directory, and configure MCP servers via a JSON file. Most daily operation is plain-English prompts. If you can edit a package.json, you can run the engine. Custom MCP servers are optional — the minimum stack uses off-the-shelf ones.
How is this different from Surfer SEO or Jasper?#
Surfer scores against a SERP-based brief. Jasper generates drafts. Neither owns the publishing layer, watches indexing, or runs a refresh queue. A content engine is the loop connecting all six stages under one agent. Surfer and Jasper are useful inside that loop; they are not the loop.
Will Google penalize content from this kind of engine?#
Google's guidance doesn't penalize AI assistance — it penalizes thin, unhelpful, or duplicative content however it was written. An engine shipping 85+ scored posts with original framing and real data sits well inside the guidelines. The risk is shipping 60-score drafts on autopilot, which is what the stage-3 gate prevents.
How many posts per week is realistic for a solo operator?#
That depends entirely on your indexed share, not your writing speed. Above 85% indexed, three to five a week is a sane ceiling including refresh. Below 70%, the correct number is zero — more posts will lower the odds for everything already waiting to be crawled.
How do I track whether my posts get cited by ChatGPT or AI Overviews?#
Three layers. Watch Search Console for inflated impressions with depressed CTR, which is the AI Overview signature. Run your core queries manually across ChatGPT, Claude, and Perplexity and log which URLs get cited. Then add a dedicated visibility tool for systematic tracking. Our AI Overview guide covers the tactics.
The takeaway#
Three points worth keeping after you close this tab.
The engine is the strategy, not the tool. Generation is cheap; compounding is rare. A working engine wins because scoring, monitoring, and refreshing are baked into the loop.
The throttle matters more than the writer. We published 29 posts in 30 days and ended with 64% of the library indexed. Output and indexing move in opposite directions past a certain rate — read your indexed share before every run.
Subdirectory or it doesn't count. Posts on someone else's domain compound for them. Posts at yourdomain.com/blog/post-slug compound for you.
Want your AI to actually publish the post it just wrote? Connect Quillly to Claude Code in under a minute — 14-day trial, no card, your own domain.